Streamlit
Sentiment analyzer
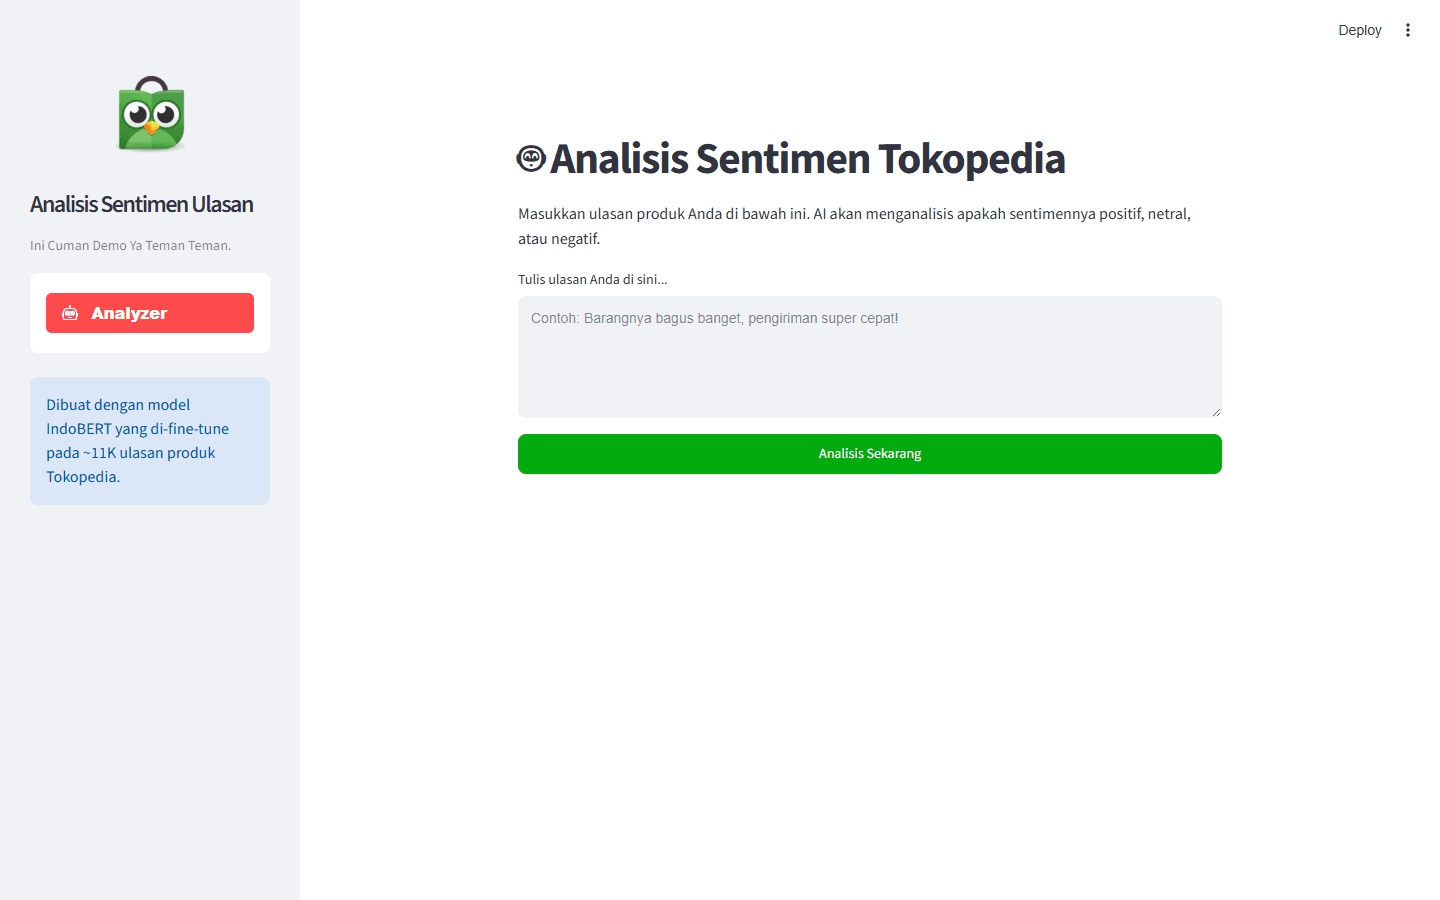
A Streamlit app that takes reviews for classification by the IndoBERT pipeline.
Case study · 08 / 08
Turning thousands of reviews into readable signals.
An NLP experiment classifying marketplace reviews as positive, neutral, or negative with IndoBERT, confidence scores, and a Streamlit interface.
Key achievement
Classified Indonesian marketplace reviews with IndoBERT, complete with confidence scores.
01 · Context
Primary users
The problem
Product review volume is too large to read one by one. Star ratings also fail to capture language context, complaints, or neutral tone in Indonesian text.
The approach
The pipeline prepares review data, tokenizes text, runs IndoBERT, and returns a sentiment class with a confidence score through Streamlit.
Key numbers
02 · My role
Data & ML Engineer
Technology used
Prepared and labeled review data for three sentiment classes.
Fine-tuned and ran inference with an IndoBERT model.
Wrapped the model in a Streamlit app that shows the class and confidence score.
Managed large models and datasets with Git LFS.
03 · Highlights
Click an image to view it larger.
Swipe through them all, tap an image to enlarge it.
A Streamlit app that takes reviews for classification by the IndoBERT pipeline.
04 · Challenges & decisions
01 / 02
05 · Outcome
Classification results can support feedback monitoring, complaint prioritization, and discovery of themes that deserve deeper analysis.
User flow
Architecture
Data
review samples · sentiment labels · preprocessing notebook
Model
IndoBERT tokenizer · PyTorch weights · three-class classifier
Inference
text input · tokenization · logits · softmax confidence
Interface
Streamlit app for exploring predictions
Data model
Review
text
rating
source
created_at
Label
review_id
sentiment
split
Model Artifact
checkpoint
tokenizer
version
Prediction
review_id
model_version
class
confidence